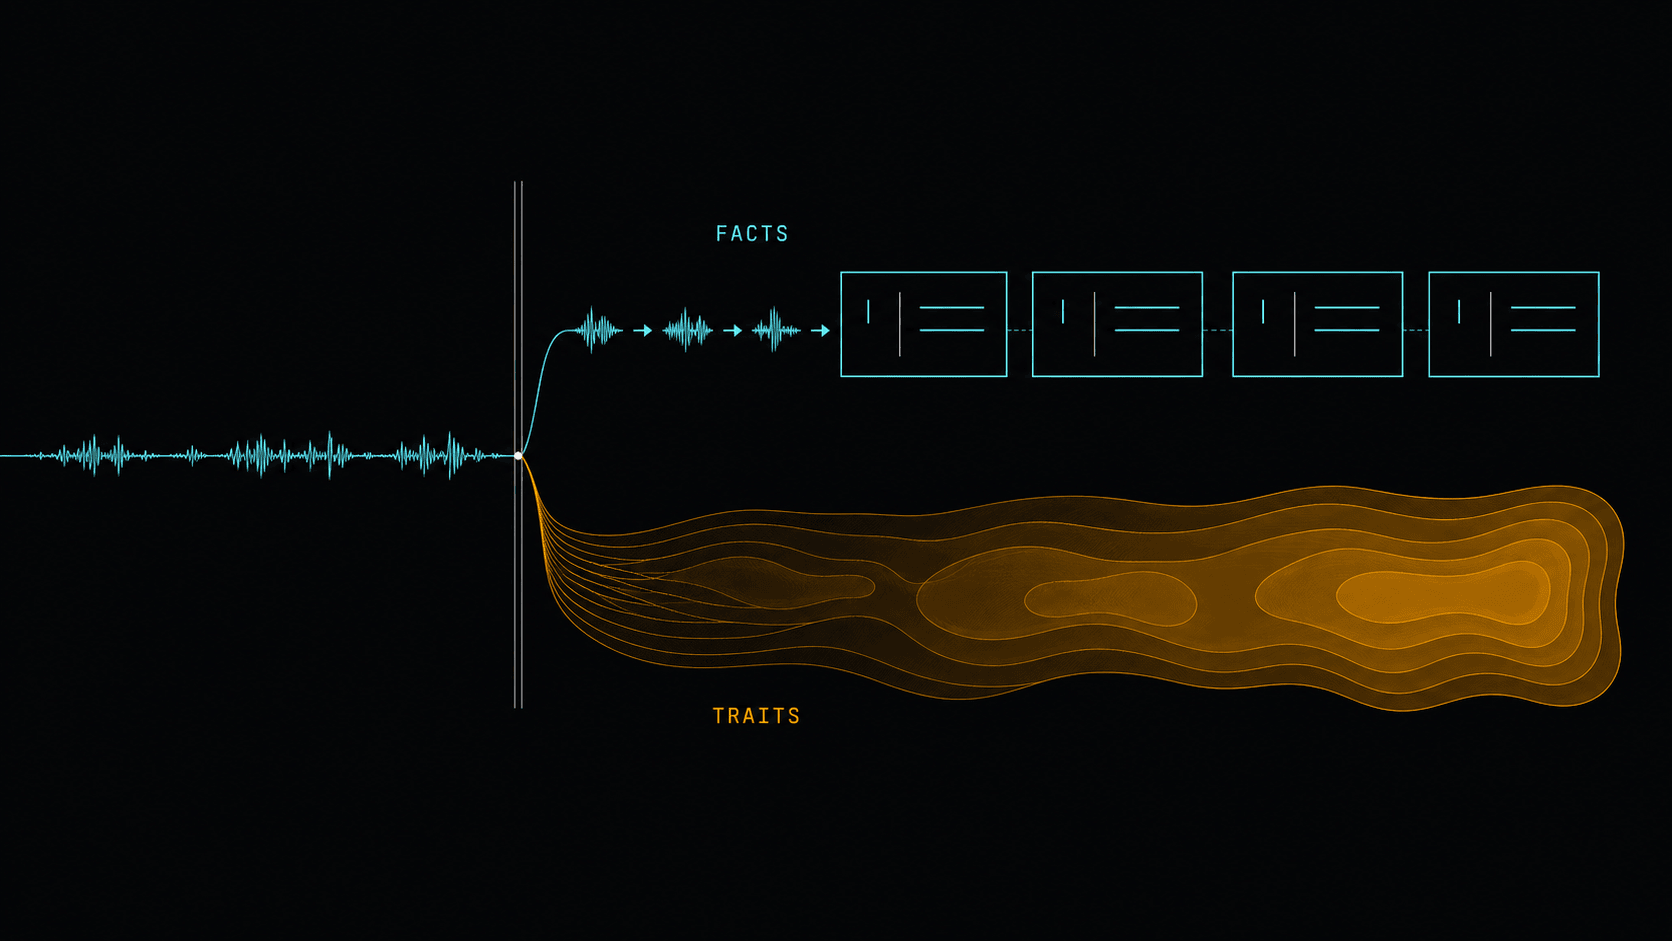
One utterance, two kinds of memory. Facts crystallise; traits diffuse.
What you get
Remembers across sessions
A caller mentions a shellfish allergy on Monday. On Friday they ask about the prawn curry and
the agent already knows.
Stays inside the turn
Embedding takes 2.2 ms p50 in process, against 232 ms for an OpenAI round trip, and 2.6 ms
p95 against 3.2 s.
No torch, no CUDA
The embedding model is 118 MB of ONNX.
onnxruntime already ships with Silero and the turn
detector, so for most agents it costs nothing new.Multi-tenant by default
tenant_id on every table and every query, with optional PostgreSQL row-level security.How it works
Reading happens inside the voice turn and makes no LLM call, and by default no network call either. The query is embedded once, ranked in pgvector, and scored, with relevant traits fetched concurrently. On the OpenAI backend it is also classified into one of seven life domains and narrowed to those candidates first. Retrieval also starts speculatively on interim transcripts, while the caller is still speaking, so the network round trip overlaps with speech instead of delaying the reply. Writing happens after the turn and never sits between the caller finishing and the agent speaking. One extraction call pulls out facts, an emotion and traits together. A second call resolves those facts against what is already stored, deciding add, update, delete or nothing.Scoring is deliberately two-part.
base_score is the raw cosine and decides the ordering.
Lexical and date bonuses only rescue a buried memory into the result set; they never
displace something that was semantically relevant to begin with.Limitations
Stated here rather than buried, because they decide whether this fits your case.Emotion comes from text, not from voice
Emotion comes from text, not from voice
The extraction model reads what was said. There is no prosody analysis, no acoustic emotion,
no voiceprint and no speaker identification. Text catches “I’m frustrated”. It cannot catch a
flat “fine” said bitterly. Upstream VoiceMem ships those features; this plugin does not,
because they require torch, funasr and modelscope.
Memory injection disables preemptive generation
Memory injection disables preemptive generation
Injecting memory changes the turn’s chat context, so LiveKit’s equivalence check fails and it
cancels the speculative generation it had already started. Preemptive generation is on by
default, so unless you turn it off you pay for a discarded LLM call every turn. The plugin
logs a warning once at startup if you have not.
Relative dates are English and Chinese only
Relative dates are English and Chinese only
“next week” expands to
August 31, 2026, matching how the extractor writes dates. Other
languages are returned unchanged, so time-scoped retrieval falls back to whatever dates
happen to appear in the memory text.The plugin owns 24 tables
The plugin owns 24 tables
They live in a dedicated
voicemem schema so they never collide with yours. The 0.x schema
is not stable between minor versions.Realtime models with server-side turn detection
Realtime models with server-side turn detection
on_user_turn_completed does not fire on those turns, so memory is neither injected nor
ingested.Start here
Quickstart
Install, migrate, and wire it into an agent. Ends with a transcript proving
it remembers across sessions.
Reference
Every
Config field, the Python API, the four protocol seams, and the CLI.Discord
Questions, and what people are building with it.
GitHub
Source, issues, and the changelog.
Attribution
VoiceMemory is derived from VoiceMem (Apache-2.0), a separate project by different authors. The prompt templates originate from mem0 (Apache-2.0). SeeNOTICE and
CHANGES-FROM-UPSTREAM.md in the repository.
Not affiliated with, endorsed by, or sponsored by LiveKit, the VoiceMem authors, or mem0.